Python modernization

Convert the Python you have. Prove the output still matches.

PyFluent modernizes pandas, PySpark, and SQL on your infrastructure. A deterministic parser converts the code, traces every column, and compares the result to the baseline. Copilot writes. The parser signs.

Built for teams who already live in Python

Not a framework directory. Not another AI IDE. A conversion and proof layer for the estate you already run.

Data engineering

pandas jobs that no longer fit memory. Move them to Polars or PySpark without rewriting by hand, and keep a map of every column.

Risk and audit

Source-to-target mappings and row-level matching a committee can read. AI suggestions are labeled; the parser is the record.

Three jobs. One engine.

The same parser architecture as MigryX, pointed at Python.

Convert

pandas ↔ Polars ↔ PySpark, plus SQL and Python version upgrades. Same input, same output, every run.

Trace

Column-level lineage and STTM extracted from the AST. No annotations, no guessed edges.

Prove

Row-level matching against the baseline you already trust. Pass, fail, and the keys that broke.

Deterministic engine

AST parse of Python, pandas, PySpark, and SQL. Lineage, mappings, and conversion are compiler work. Re-run Monday or Friday; the result does not drift.

AI, with a leash

Explains, documents, and suggests. The parser validates before anything ships. Turn AI off and conversion, lineage, and matching still run.

See the work, not a deck

Lineage beside the code. Validation against the baseline. Docs generated from the parse, not from a prompt.

Lineage and project metrics
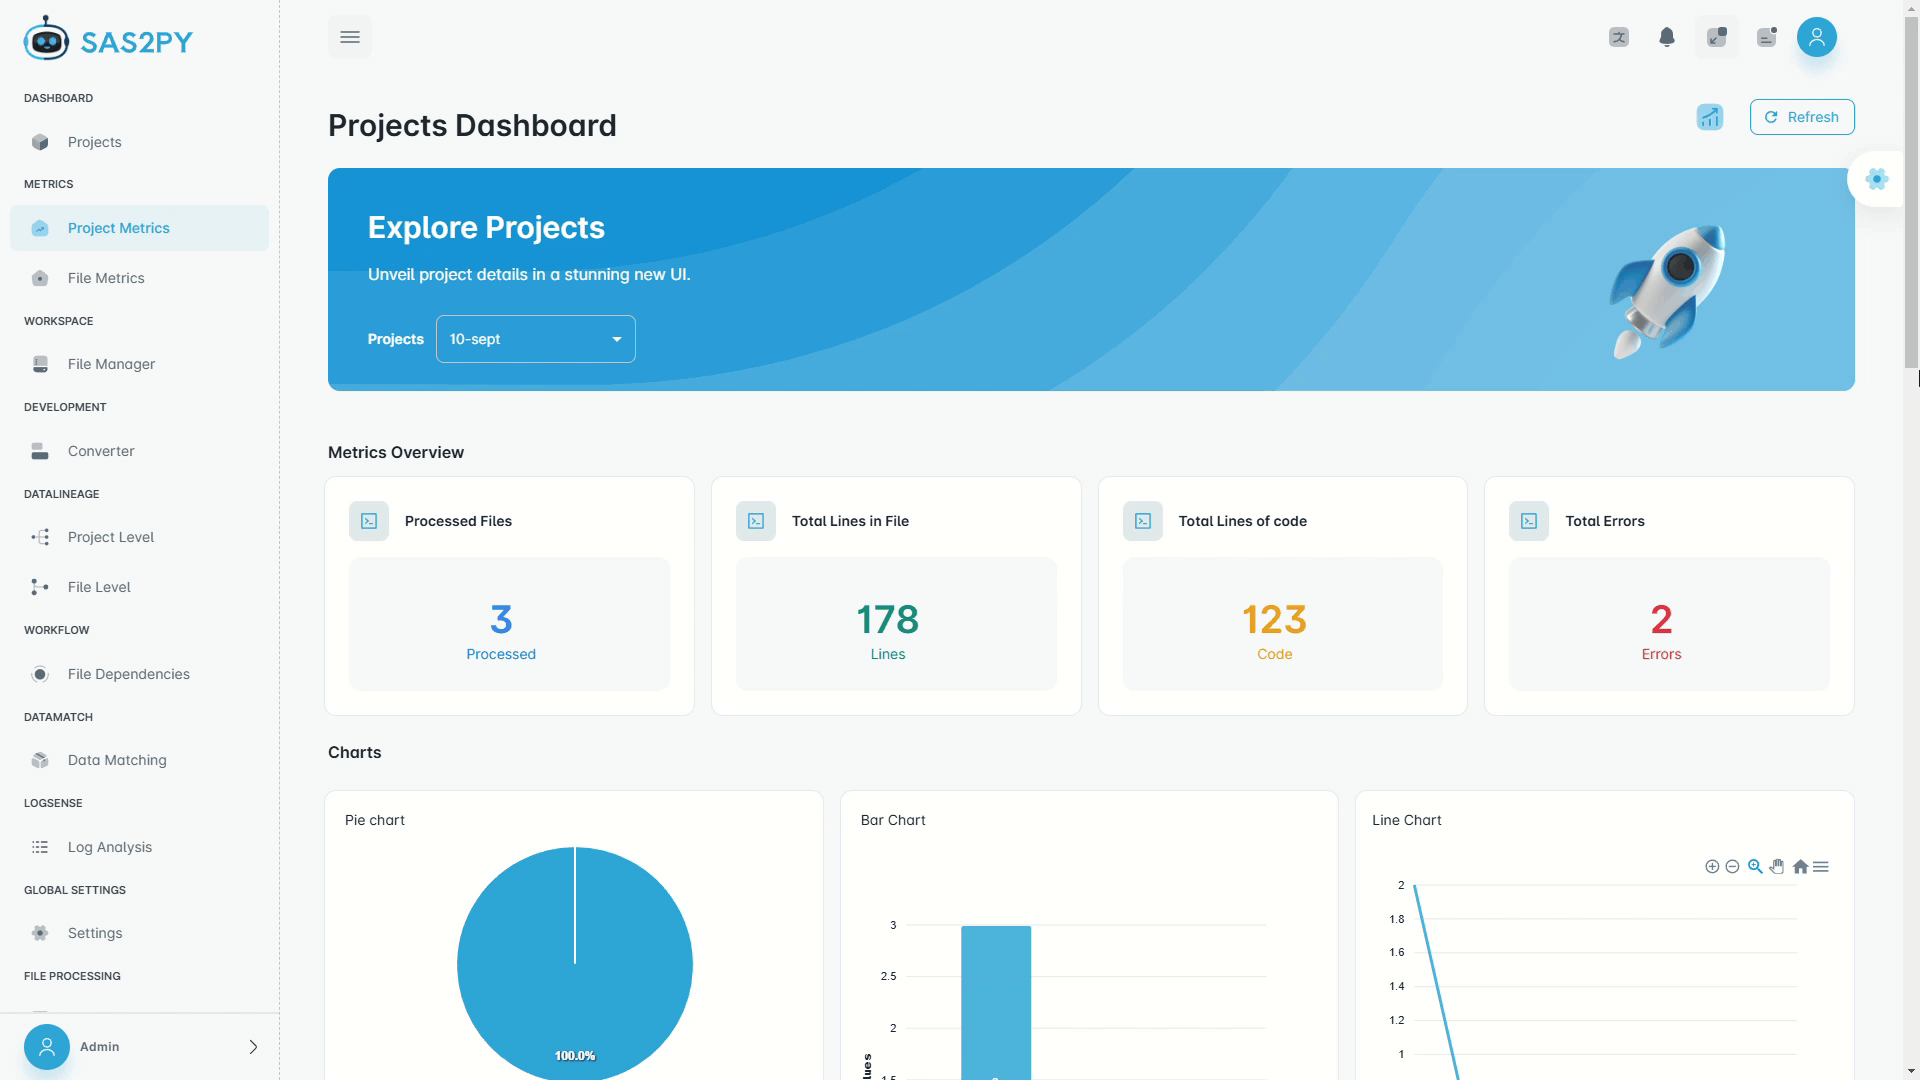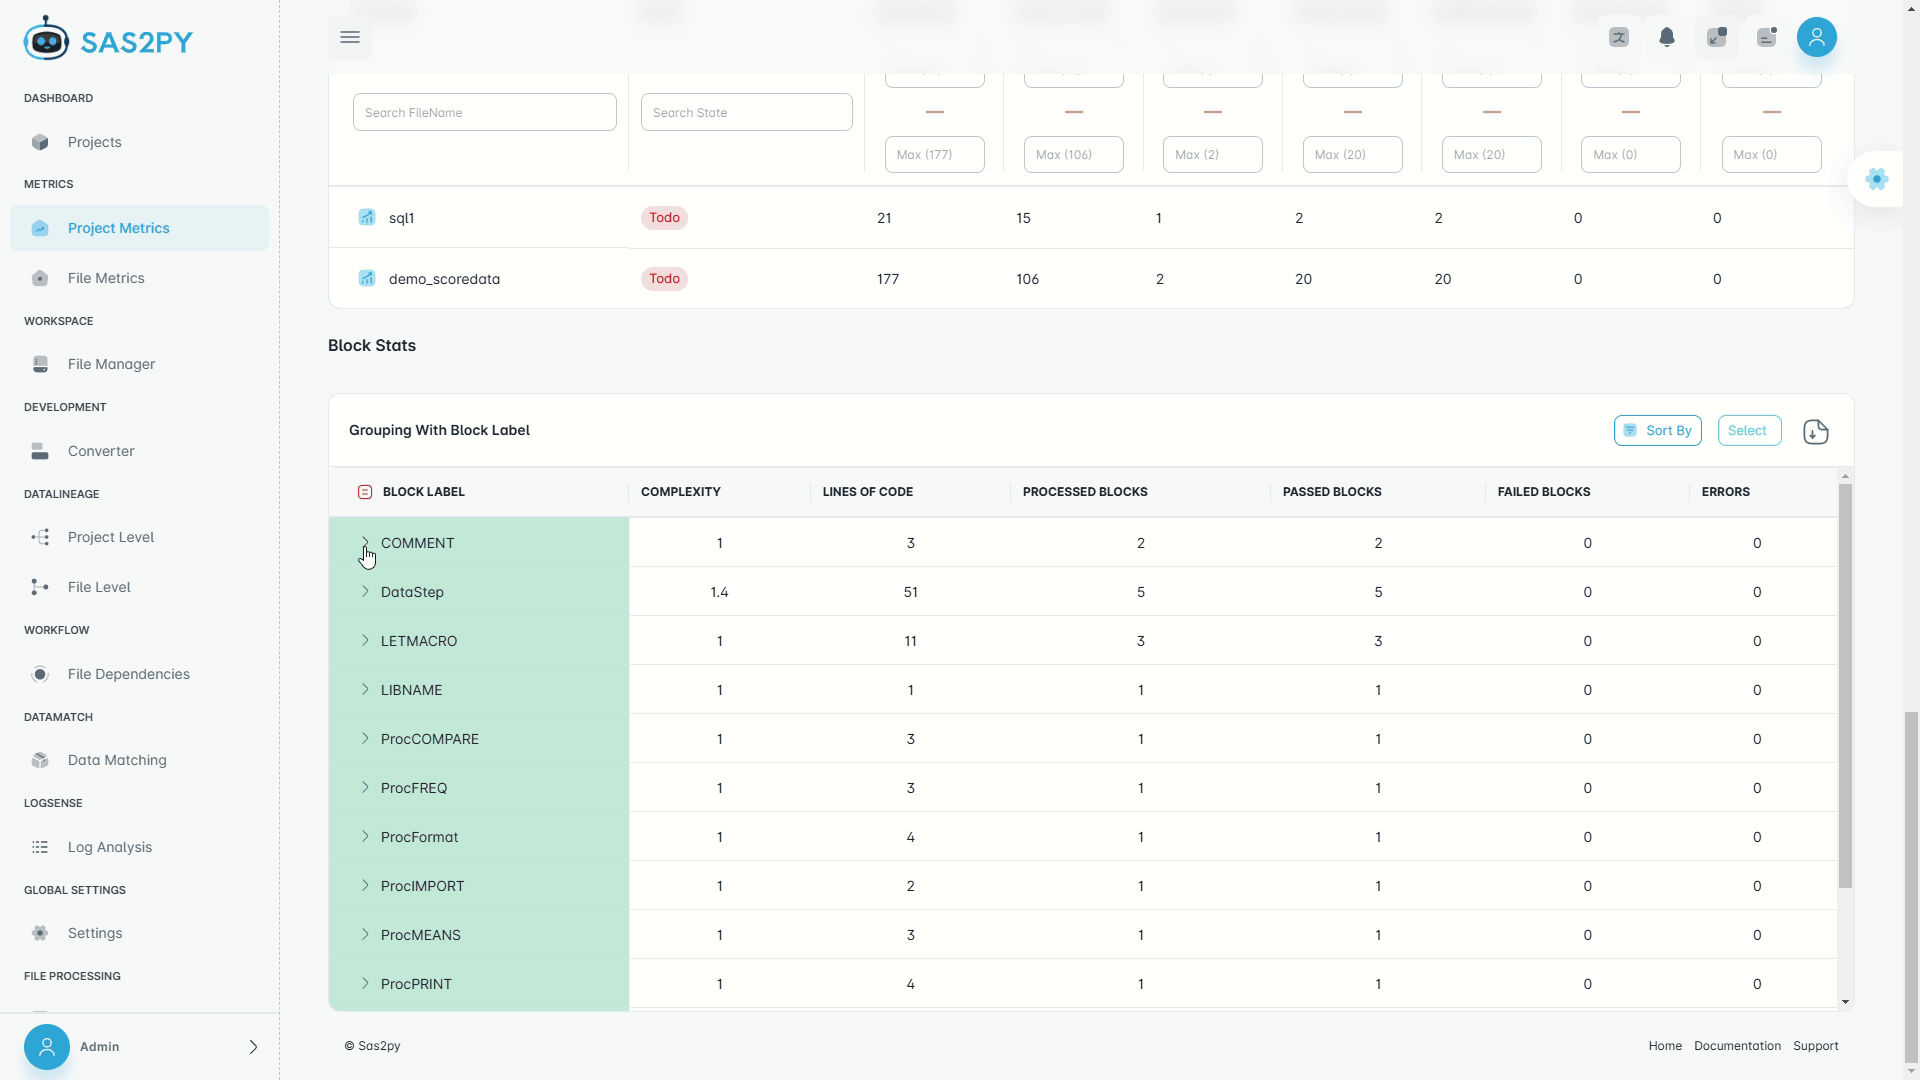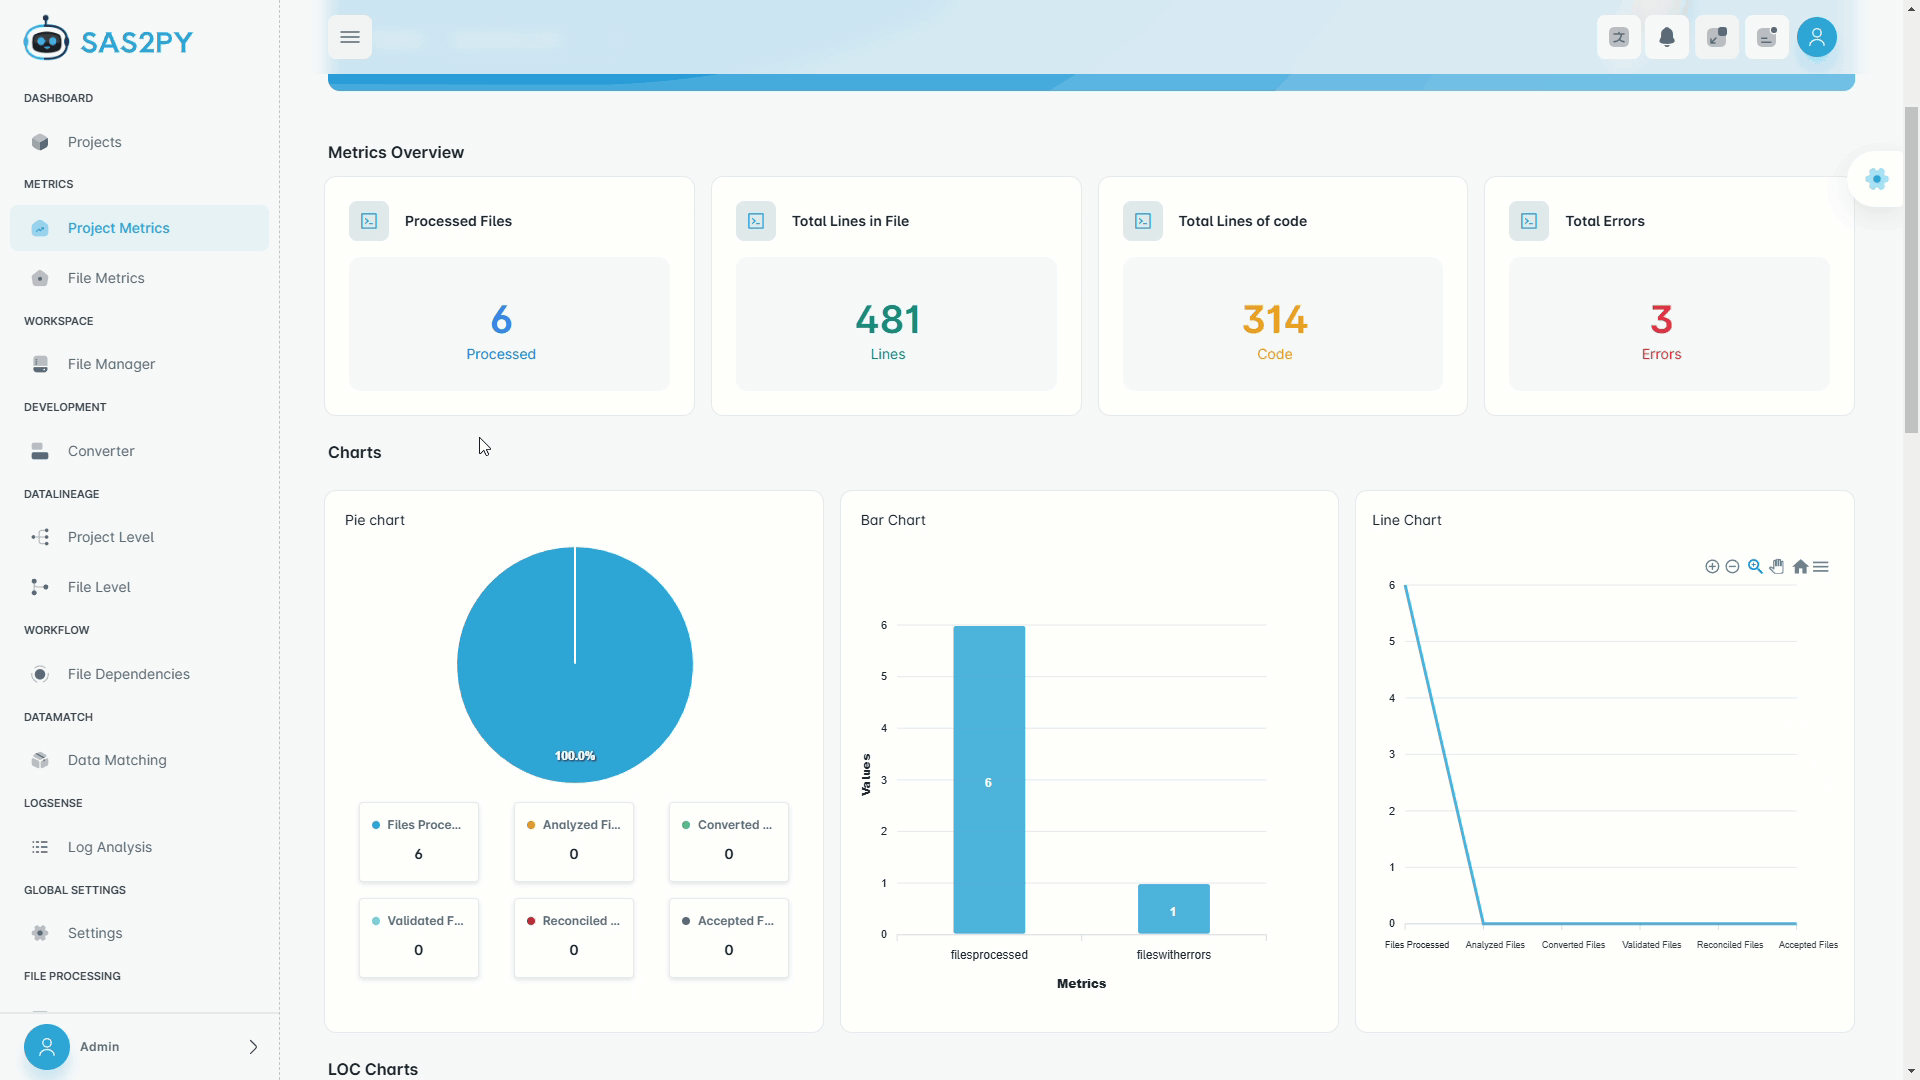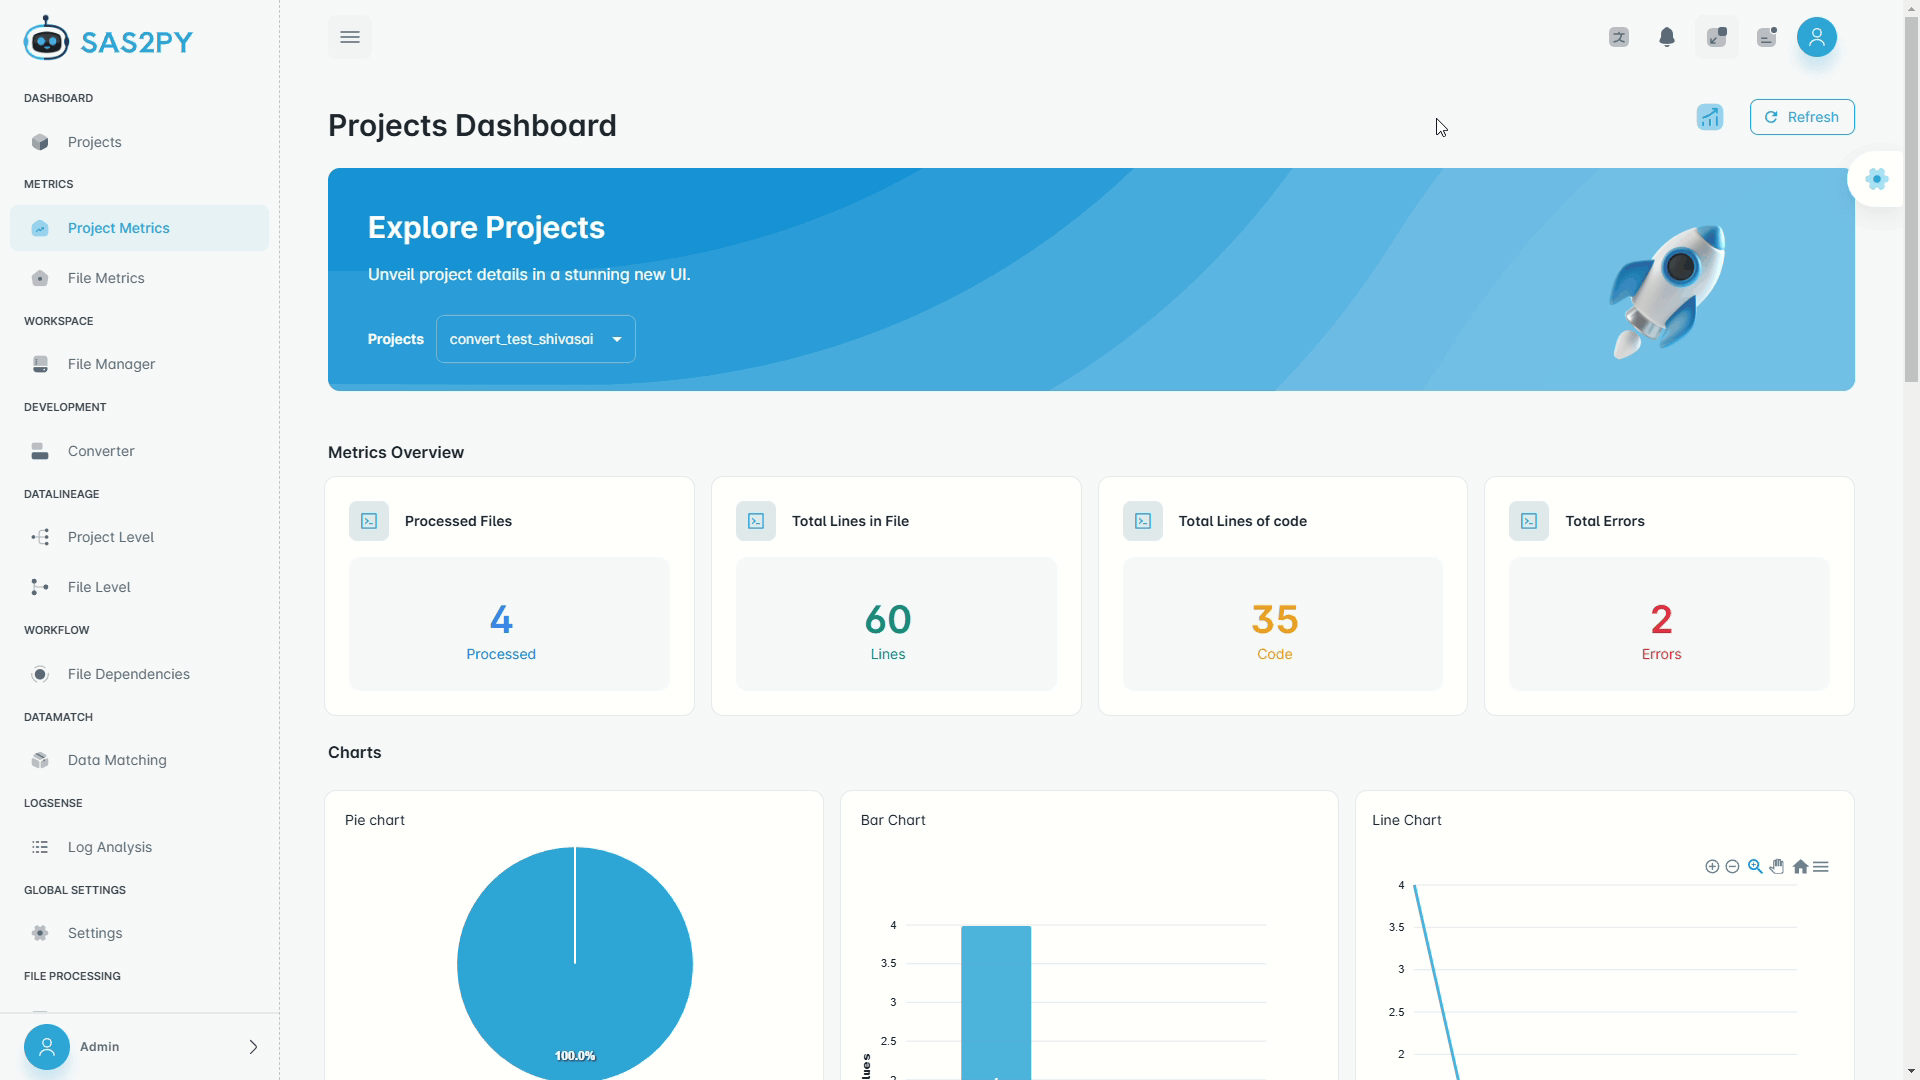
Project metrics and visual lineage in PyFluent Studio
Data matching
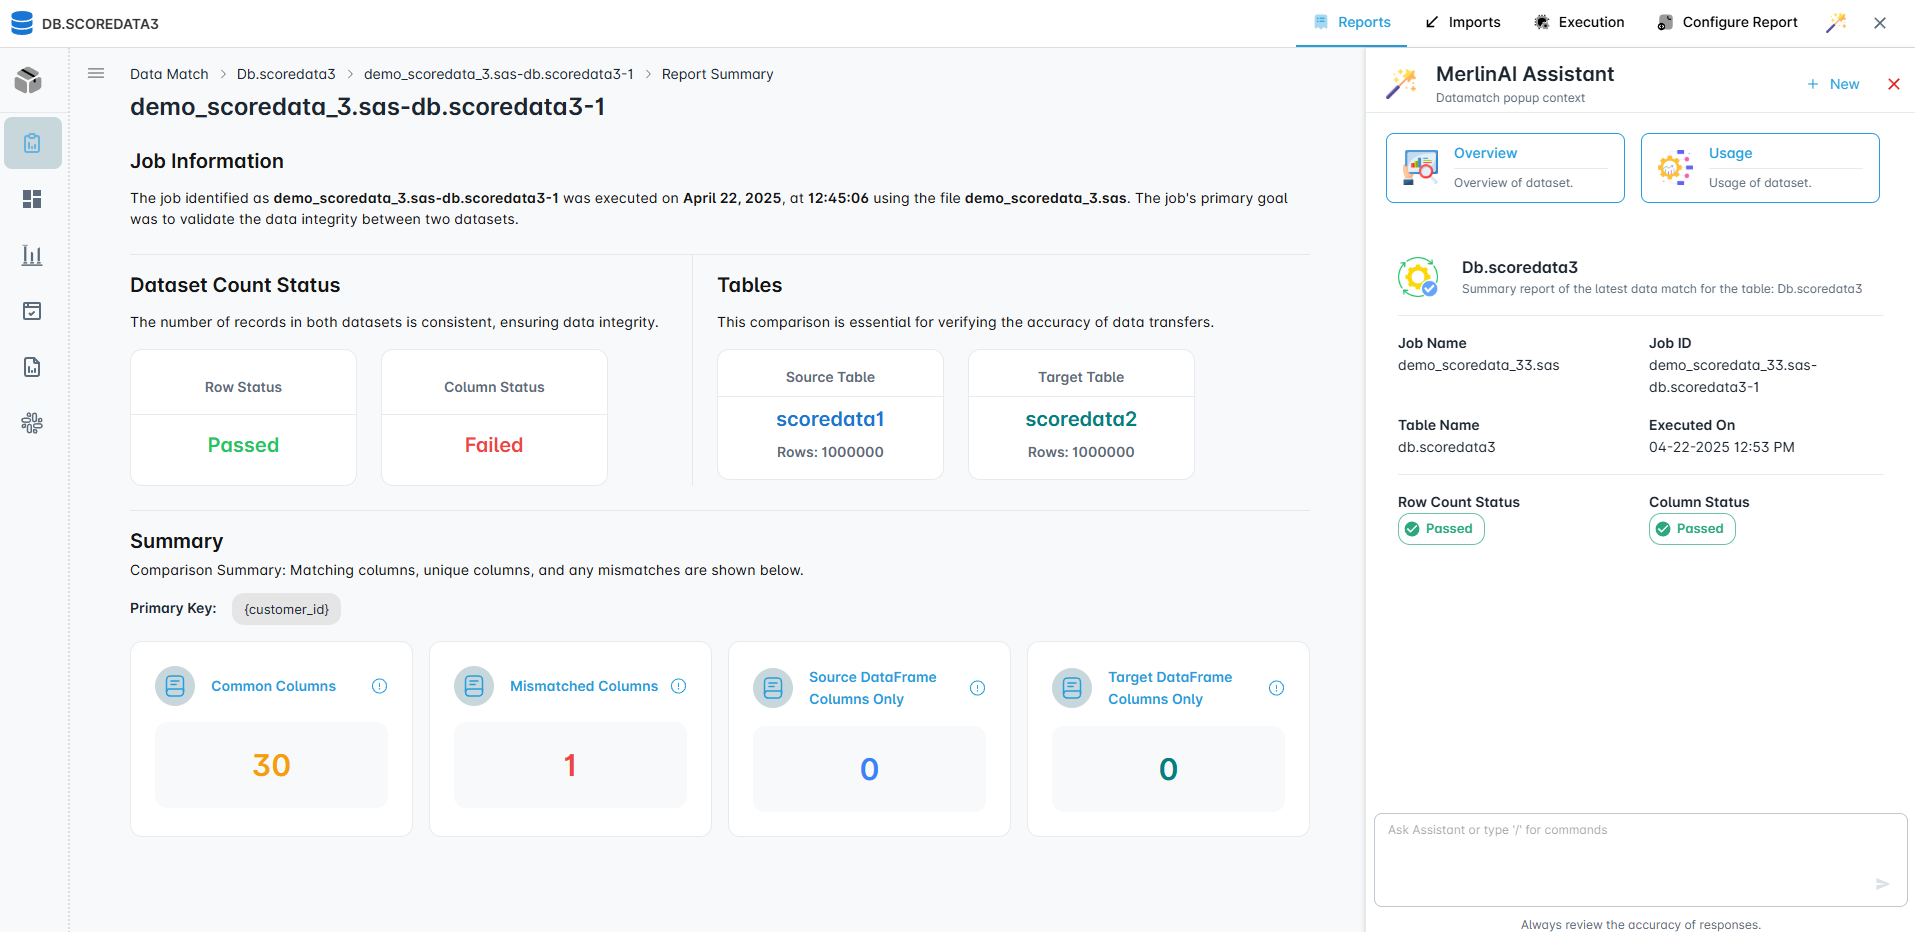
Column-level validation results

Studio walkthrough: analyze, convert, validate, deploy →

What Copilot and a notebook do not do

Use them. They stop where a regulated conversion cannot.

JobAI IDE / notebookPyFluent
Rewrite pandas to Polars or PySparkA suggestion you review by eyeA parser conversion you can re-run
Column lineageNot producedExtracted from the AST, no annotations
Proof the output matchesA cell you hope is rightRow-level matching against the baseline
Where it runsYour laptop, or a vendor cloudSaaS or self-hosted, air-gapped if required

Pick the target. The engine does the rest.

These are conversion paths, not a catalog of every Python library.

pandas → Polars

Same logic, multi-threaded runtime. Lineage stays attached to the new frames.

PySpark → Snowflake / Databricks SQL

When the warehouse is the target and the job should not stay a cluster notebook.

SaaS or self-hosted. Same product.

Install the image, or use the MigryX portal. Your code does not leave the network you pick.

Self-hosted

Docker or Kubernetes behind your firewall. Air-gapped capable. No telemetry required.

SaaS

Same engine on the MigryX portal. Use it when the estate is allowed off-network.

The source is not Python?

That is a different product, same company.

Start on a sample of your code

Start with a sample of your code, or book a demo and we will walk a job you already run.

hello@pyfluent.ai · Indianapolis · Hyderabad